Audio and speech recognition

The agent heard two voices. It thought both were the customer.

A phone call arrives as a single audio channel, and everything the microphone picks up ends up in it: the customer, whoever is sitting at the kitchen table, the radio – and the agent's own voice coming back. Why that is one of the hardest problems in a voice agent, explained without the jargon.

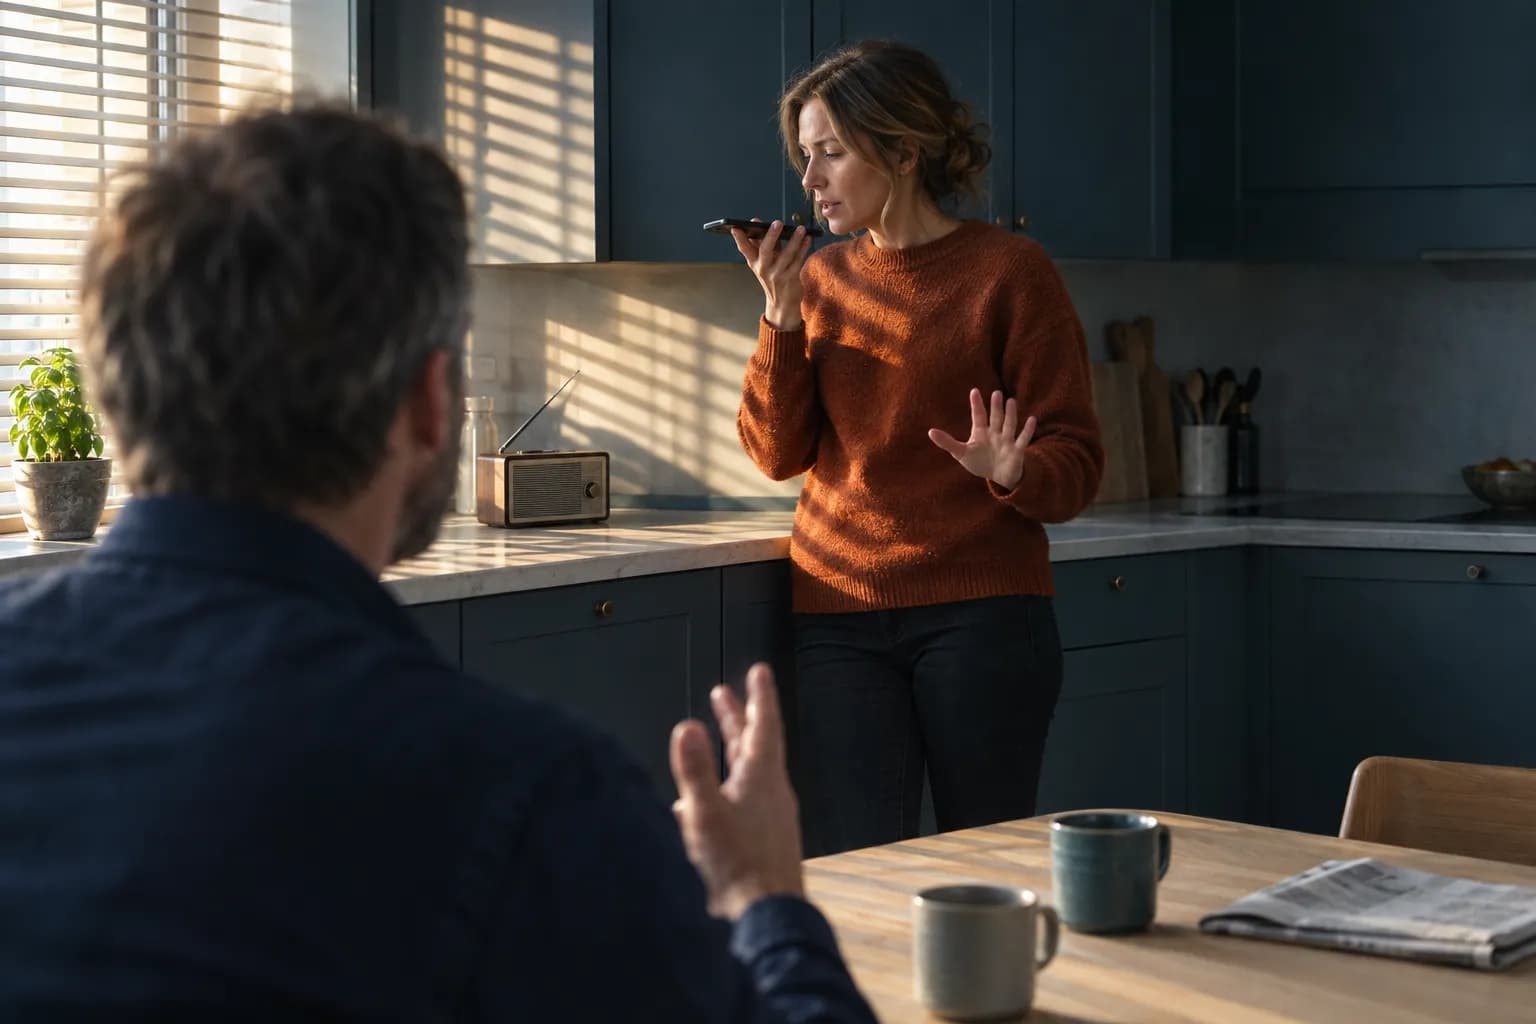
Over the shoulder of a man at a kitchen table: a woman in a rust-coloured knit jumper stands at the counter speaking into a mobile phone she holds flat in front of her mouth, her other hand raised towards the man, who is gesturing at her. Afternoon sun through blinds falls across the counter and a small radio.

The customer calls to move an appointment. She is standing at the kitchen counter with the phone on speaker. The agent offers Thursday at 2 pm. She says "yes, that …", and at the same moment her husband at the table says "no, Thursday we're going to my mother's".

The agent has received two answers to one question, from two people, in the same audio stream. It doesn't know there are two.

On Monday, 28 September, Fish Audio launched transcribe-1-pro, a transcription model that labels who is speaking in a recording. It inserts numbered speaker tags and markers such as "[laughter]" straight into the text, at $0.36 per audio hour. That is useful. It is also a good way into explaining why the problem is so much harder while the call is happening than afterwards.

One channel, every voice

An ordinary phone call is a single audio channel. The phone captures what its microphone hears and sends it on as one stream. There is no separate track for the customer and another for the rest of the room. The line also throws away a good part of the sound on the way, so what reaches the agent is both narrower and more mixed than what the customer hears herself.

Speech recognition does what it was built to do: it writes down speech. It does not distinguish between speech meant for the agent and speech that just happens nearby. Four sources come up again and again:

What is in the room What the agent gets wrong What helps
Another person talking Takes a remark to the customer as an answer Reading important details back and waiting for a yes
Radio, TV or music in the background Transcribes words nobody said to it, or thinks the customer is interrupting Requiring more than a couple of syllables before the agent stops
The agent's own voice coming back Hears itself and interrupts itself Echo cancellation, tested on speakerphone and in a car
An open-plan office Mixes in colleagues' conversations Coping when the customer says "hang on"

The agent that interrupts itself

The third row surprises people most. When the customer has the phone on speaker or talks through the car's hands-free system, the agent's voice comes out of a loudspeaker a few centimetres from the microphone. The phone tries to subtract that sound again – this is called echo cancellation – and it is good, but not flawless. Whatever slips through goes back to the agent.

An agent configured to stop talking the moment it hears speech then does exactly that: it stops mid-sentence because it heard itself. To the customer it sounds like an agent that stutters, or one that never lets her hear a complete answer.

The same setting decides what happens with the radio. Set the threshold too low and the agent stops for every voice in the background. Set it too high and it talks over the customer when she really does want to interrupt. There is no single right value. It has to be tried on the calls you actually get.
Want to talk it through with someone who has done this before?

Fifteen minutes on a call. We will tell you honestly whether a voice agent fits your setup – and what has to be settled before it goes live.

15 minutes · no obligation · pick your own time

Why it is easier afterwards

Separating speakers in a finished recording is a different task from doing it while the call is live. Afterwards, the model has the whole conversation. It can hear voice number two come back again and again, compare, and go back. During the call, the agent has a few syllables and a fraction of a second to decide whether to respond.

Fish Audio itself notes that the speaker numbers only apply within a single recording. They don't say who the person is – or which of them is holding the phone.

That doesn't make the labelling worthless. It belongs in the review afterwards. With speaker tags in the record of what your agent said, you can find the calls where a voice other than the customer's drove the outcome. That is a better starting point for tuning the setup than an overall error rate.

The fix isn't only audio processing

The most robust solution lies in conversation design. Every beat of a call has its own point where it can break, and here three habits handle most of it:

Confirm whatever costs something. Times, dates, names and amounts are read back, and the agent waits for a clear yes: "So I'm moving your appointment to Friday at ten. Is that right?" A question addressed directly to the caller is usually answered by the caller.

Notice contradictions. If two different answers to the same question arrive within a couple of seconds, that is a signal in itself. The agent should ask once more rather than pick the last thing it heard.

Handle "hang on". Customers often talk to someone else in the middle of a call. An agent that understands "hang on" and "I just need to ask my husband", and then waits instead of interpreting whatever is said next, has solved a large part of the problem.

Test it where your customers actually call from

A setup tested from a quiet meeting room with headphones has been tested under the best conditions it will ever meet. Instead, call your own number from a car on hands-free, from the kitchen with the radio on, and with the phone on speaker while a colleague talks next to you. Listen for whether the agent stops when it shouldn't. Read the transcript afterwards: are there words in it that nobody said to the agent?

Customers rarely call from a quiet room. The agent only hears one line, but it has to behave as if it knows it isn't alone in the conversation.

Threll.ai builds voice agents in Norwegian, Swedish and Danish. The test above takes half an hour, and you can run it today.